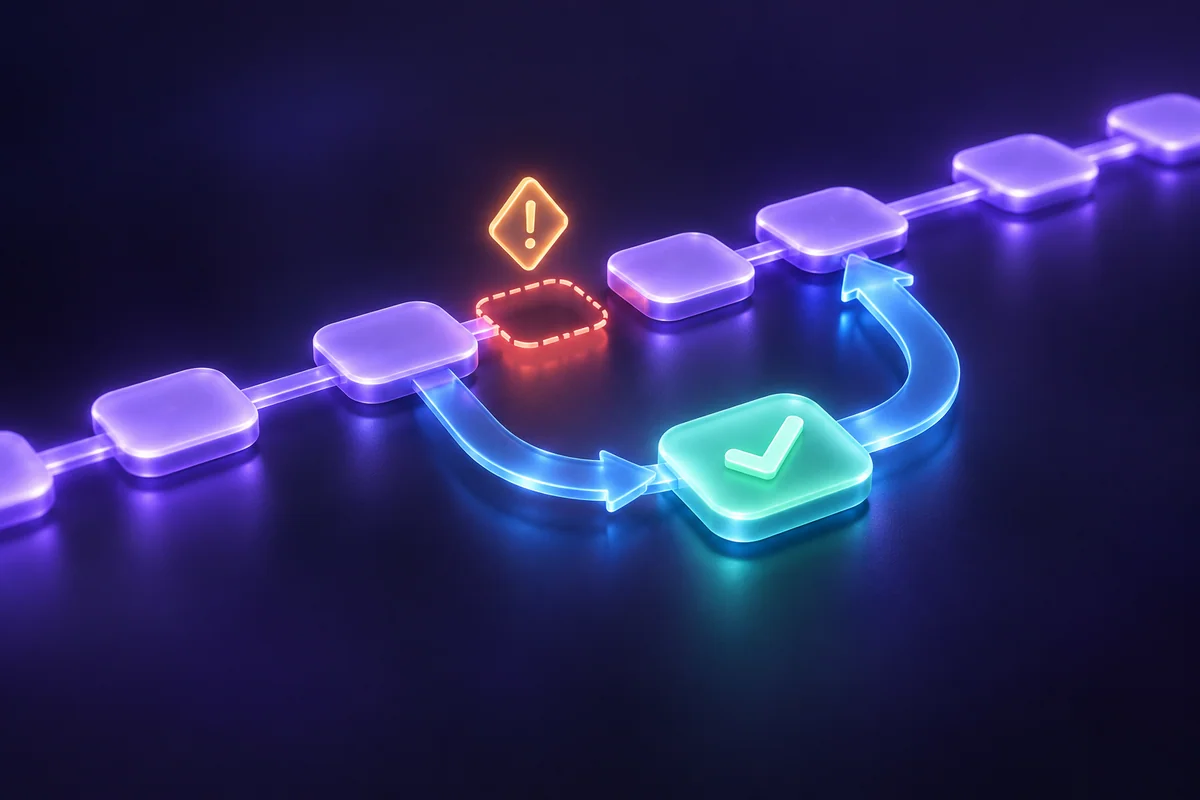
Keep the input, identify the last confirmed step, tell the right person what failed, and retry only when it is safe. Always provide a way to pause and complete urgent work manually.
- Keep the input
- Find the failed step
- Check what completed
- Recover safely
- Confirm the result
1. Separate three different problems
Missing input, temporary unavailability, and uncertain delivery need different responses. Retrying an invoice with no customer address will not supply the address. Waiting and retrying may help when an app is briefly unavailable. A message that timed out needs an extra check because it might already have been sent.
Write these cases in plain language in the project scope. A non-technical teammate should be able to tell the difference between Needs information, Waiting to retry, and Check destination before retry. Avoid treating every error as a reason to restart the whole workflow.
| What happened | A sensible next step |
|---|---|
| Required information is missing | Ask the owner to correct the input |
| The destination is temporarily unavailable | Wait and retry within an agreed limit |
| Delivery timed out | Check the destination before sending again |
| Permission was removed | Pause and have the account owner restore access |
| The same item failed repeatedly | Stop automatic retries and ask for review |
2. Keep enough information to recover
Give each run a reference and record when it started, which input it used, what finished, and where it stopped. Keep a link to the original record where appropriate. Someone investigating later should not have to reconstruct the work from several notification emails.
Keep logs proportionate to the job. A reference number and a short error description may be enough; copying full customer messages or confidential files into every alert usually is not. Decide who may read the log, how long it stays available, and where any sensitive source information belongs.
3. Send an alert that tells someone what to do
A message saying Automation failed makes the recipient investigate from scratch. A better message names the workflow, identifies the affected item, states the last confirmed step, and gives the next action. Send it to a responsible owner and nominate a backup.
For an illustrative document workflow, the alert could say: Draft D-042 was created, but the review notification was not confirmed. Check the reviewer inbox before resending the notification. Do not generate another draft. This explains both what happened and what would make recovery worse.
4. Check before repeating an action
Some actions only read information. Others send a message, create a document, or change a record. Repeating those changes can have consequences even when the automation tool shows an error. A timeout means the tool did not receive a timely response; it does not by itself prove that the destination did nothing.
Use a stable item reference and a destination lookup where supported. If the original item already exists, continue from it rather than creating a second copy. For actions where you cannot reliably check the outcome, route the uncertainty to a person. Zapier explicitly warns that replaying timed-out actions can create duplicates.
- Confirm the last successful step.
- Look for an existing destination record or receipt.
- Retry only the unfinished safe step where supported.
- Set a retry limit and wait between attempts.
- Stop and ask a person when the outcome is uncertain.
5. Keep a simple manual route
The fallback should explain how to pause new runs, find waiting items, and complete urgent tasks outside the automation. It should also show how to mark manually completed items so they do not run again when the system recovers. A pause button is useful only when the team knows what it pauses.
For low-volume work, the fallback might be a small review sheet with Pending, Completed manually, and Safe to retry columns. Test this with a harmless sample. If only the original builder can recover a failed run, the handover is not yet complete.
6. Test recovery as part of the pilot
Deliberately test a missing field, an unavailable test destination, a repeated event, and a permission failure in an agreed safe environment. The aim is to see the alert, find the input, make the right decision, and verify the final state. A test passes when recovery is understandable, not merely when the next run turns green.
Record who receives alerts, what support is included, and which failures require the account owner. Review the most common failures during the pilot. A recurring problem may call for a better input check or a simpler workflow rather than more automatic retries.
Your ready-to-use checklist
0 of 6 checked For your own planning
Your ticks stay in this open page only. No answers are sent to us.
Make the next step clear.
Use this brief with your team or an automation partner. Leave out passwords and confidential customer information.
Copy this recovery note
Free templateSources and notes
Technical references checked on September 19, 2026. Product features and plans can change.
- Zapier: duplicate data and timeouts
Explains the duplicate risk after timeout replays.
- Zapier: replaying runs
A platform-specific example of replay controls. Available behavior depends on the platform and plan; this article's recovery plan is tool-neutral.